
Build an AI Agent Evaluation System with DeepEval & LangChain (Full Project, step-by-step)
Build and evaluate a refund AI agent with Python, LangChain, OpenAI, and DeepEval. In this hands-on tutorial, you'll build a customer support agent that handles refund requests, then create an evaluation workflow to measure how well it performs. The agent uses tools to look up customer purchases, check refund eligibility, calculate refund amounts, and generate simulated refund tickets. You'll connect these tools to a LangChain agent with conversation memory and structured responses. Then we'll evaluate both the agent's answers and the actions it takes. Did it choose the right tools? Pass the correct arguments? Follow the refund policy? Complete the task without unnecessary steps? You'll learn how to turn these questions into measurable tests using seven DeepEval metrics, inspect failures, and use the results to guide agent improvements. By the end, you'll have an AI engineering portfolio project that demonstrates tool use, agent tracing, evaluation datasets, and data-driven iteration. What you'll learn: • Build a refund support agent with LangChain and OpenAI • Define Python tools for customer lookup, date checks, refund calculations, and simulated tickets • Add conversation memory and structured outputs with Pydantic • Translate business rules into agent instructions and evaluation scenarios • Create test cases with expected answers and expected tool calls • Capture agent execution traces with DeepEval's LangChain integration • Evaluate individual metrics before combining them into a complete workflow • Inspect scores, pass rates, and explanations to understand failures • Use evaluation results to improve prompts, tool use, and agent behavior We'll explore seven evaluation metrics: • Task completion: Did the agent accomplish the user's task? • Step efficiency: Did it avoid unnecessary or redundant steps? • Plan quality: Was its plan suitable for the task? • Plan adherence: Did its execution follow the plan? • Tool correctness: Did it call the expected tools? • Argument correctness: Did it pass appropriate inputs to those tools? • Answer correctness with GEval: Did its final answer reach the expected conclusion? The project includes eight refund evaluation scenarios covering eligible refunds, purchases outside the refund window, requests for specific items, multiple-item refunds, information-only questions, missing usernames, unknown customers, and items the customer never purchased. These cases help reveal problems that a successful demo can miss. An agent might give a convincing answer while selecting the wrong tool, calculating the wrong amount, or issuing a ticket when the user only asked a question. We'll also discuss how to interpret evaluation failures. A low score can point to an agent mistake, an inconsistent expected answer, missing evaluation evidence, or a rubric that needs refinement. Reading the traces and explanations helps you decide what to change. Tech stack: Python 3.12+, LangChain, LangGraph memory, OpenAI, DeepEval, Pydantic, python-dotenv, and uv. If you're learning AI agents, LLM evaluation, tool calling, customer support automation, or backend AI engineering, this tutorial shows how to build an agent and measure its behavior in a repeatable workflow. Timeline: 00:00 - Intro 01:30 - Project overview 02:45 - Understanding the refund agent 05:10 - Building the refund agent for businesses 1:09:06 - Evaluation metrics and DeepEval 2:32:50 - Combining all evaluation metrics 2:38:30 - Data-driven decisions and agent improvements GitHub repository: https://github.com/Mohamad-Hachem/LangChain_Agent_Evaluation_System Previous tutorial — RAG Evaluation System: https://youtu.be/n_Oc-Wq_KqI Subscribe for more hands-on tutorials on AI agents, evaluation, RAG, and Python AI engineering. #AIAgents #LangChain #DeepEval #LLMEvaluation #Python #OpenAI #AIEngineering #AgentEvaluation #ToolCalling #AIProjects
Suggested videos
How to Setup DeepEval for Fast, Easy, and Powerful LLM Evaluations
Leon Builds Agents · 9:05
Renaming and Combining | Pandas & Machine Learning Lesson 6 | AI Career Lab
AI Career Lab · 2:20
Build a RAG Evaluation System with DeepEval (Full Project, step-by-step)
AI Career Lab · 3:12:01
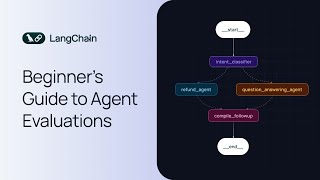
Beginner's Guide to Agent Evaluations
LangChain · 40:45
Ultimate LangGraph Crash Course 2026 (Step-By-Step)
AI Career Lab · 2:17:10
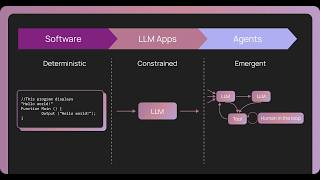
Observability and Evals for AI Agents: A Simple Breakdown
LangChain · 14:45
Build MCP Server for AI application(Full Project, step-by-step)
AI Career Lab · 1:24:06
How to Systematically Setup LLM Evals (Metrics, Unit Tests, LLM-as-a-Judge)
Dave Ebbelaar · 55:02
Data Types and Missing Values | Pandas & Machine Learning Lesson 5 | AI Career Lab
AI Career Lab · 2:33
LLM as a Judge: Scaling AI Evaluation Strategies
IBM Technology · 6:09
Python Environment Setup | Section 1 | Free Python Course | AI Career Lab
AI Career Lab · 7:08

LLM evaluation 2026 | DeepEval | Langchain | Open-Source | Healthcare AI
VGI Skill Lab · 15:51